Artificial intelligence works by finding patterns in huge amounts of data and then using those patterns to make predictions, decisions, or new content. So how does artificial intelligence work in a way a non-engineer can follow? It adjusts millions or billions of internal numbers until its guesses become good enough to be useful, and it does not think the way a person does.
That single idea explains most of what you see, from the spam filter in a Gmail inbox to a chatbot that drafts a cover letter. This guide covers the data, the training process, and the model types behind modern AI, then shows where these systems fail and how to tell what kind of AI sits behind a product.
One Loop Behind Nearly Every AI System
Every AI system, from a basic spam filter to a large language model, runs the same loop. It looks at an example, makes a guess, checks how wrong the guess was, and adjusts its internal settings so the next guess is slightly better. Repeat that millions of times and the system gets good at the task.
Nobody writes the rules by hand. A traditional program says “if the email contains this phrase, flag it as spam.” An AI system studies thousands of emails already labeled spam or not spam and works out its own rules, many of which no human would think to write.
The label is older than most people assume. John McCarthy and his co-authors used “artificial intelligence” in their 1955 proposal for the 1956 Dartmouth summer workshop, usually treated as the field’s starting point. The math has existed for decades, but cheap computing power and giant datasets only made it practical in the last fifteen years or so.
AI, Machine Learning, and Deep Learning: How They Fit Together
These terms get used as if they mean the same thing. They are nested, like boxes inside boxes.
Artificial intelligence is the outer box. It covers any software that does something we would normally expect to need human judgment, including old rule-based programs such as early chess engines and tax-filing wizards.
Machine learning sits inside it and covers systems that learn from data instead of following hand-written rules. Deep learning sits inside machine learning and uses neural networks with many layers. Most of today’s headline tools, including image generators, voice assistants, and chatbots, run on deep learning.
Generative AI is a further slice. It produces new text, images, audio, or code instead of only sorting or scoring things that already exist.
The Four Ingredients Every AI System Needs
Strip away the brand names, and every system needs the same four things.
1. Data
Data is the raw material. An image model that recognizes cats has seen millions of labeled photos, and a language model has read a large share of the public web, books, and code. Quality matters more than most people expect, because the model absorbs every pattern in the data, including the mistakes.
Teams also clean it first. They remove duplicates, fix wrong labels, and filter out junk, and that unglamorous work often decides whether a project succeeds.
2. Algorithms and Models
The algorithm is the learning recipe. The model is what comes out: a large file of numbers, called parameters or weights, that stores what the system picked up. OpenAI’s 2020 GPT-3 paper described a model with 175 billion parameters, and companies have since become less open about the sizes of their newest models.
3. Computing Power
Training involves an enormous amount of arithmetic, so it runs on graphics processing units (GPUs) and similar chips that perform many calculations at once. Large training runs use thousands of these chips for weeks, which is why a small group of big companies and cloud providers train the largest models.
4. A Goal the System Can Measure
The system needs a score that says how well it is doing. For a spam filter, that is the share of emails sorted correctly. For a chatbot, it is how well the model predicts the next piece of text. Without a clear score, there is nothing to improve against.
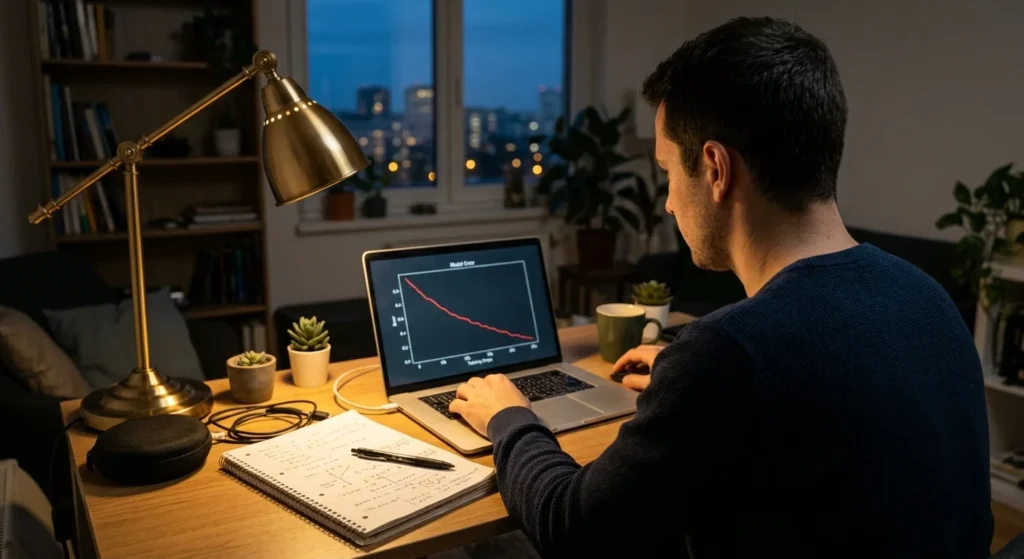
How AI Learns During Training
Guess, Measure, Adjust
Take a toy example. A spam filter starts with random settings, reads an email, and outputs a probability that it is spam. At first, that probability is close to a coin flip.
The email really was spam, so the error is large. A method called backpropagation, popularized in a 1986 Nature paper by David Rumelhart, Geoffrey Hinton, and Ronald Williams, works out which settings contributed most to the error. Gradient descent then nudges each one a tiny amount in the direction that shrinks it.
After a few million emails, the settings have moved from random noise to something that reliably separates spam from real mail. Image classifiers and language models train the same way. Only the data, the size, and the way error is measured change.
Three Ways Machines Learn
Supervised learning uses labeled examples, such as photos tagged “cat” or “dog.” It powers many spam filters, fraud detection systems, and medical imaging tools.
Unsupervised learning has no labels. The system looks for structure on its own, such as grouping customers with similar buying habits.
Reinforcement learning rewards good outcomes and penalizes bad ones. DeepMind’s AlphaGo combined it with other methods to beat top Go player Lee Sedol in 2016, and the same idea is used to tune chatbot behavior.
Neural Networks Explained Without the Math
A neural network is a stack of layers. Each layer holds small units that take in numbers, multiply them by weights, add the results, and pass them forward. Early layers pick up simple features, and later layers combine those into bigger ideas.
In an image model, early layers tend to respond to edges, middle layers to shapes such as eyes or wheels, and the final layers to whole objects. Nobody programs those layers to look for edges. The behavior emerges from training.
The modern deep learning era is often dated to 2012, when AlexNet, built by Alex Krizhevsky, Ilya Sutskever, and Geoffrey Hinton, won the ImageNet recognition contest by a wide margin. Hinton, Yann LeCun, and Yoshua Bengio later shared the 2018 Turing Award for their work on deep learning.
How Chatbots Like ChatGPT Actually Work
Large language models, the engine behind ChatGPT, Claude, and Gemini, feel different from older AI, so they deserve their own explanation. So how does artificial intelligence work when the output is a paragraph instead of a label?
Tokens and Next-Word Prediction
A language model splits text into tokens, which are short words or pieces of longer ones. Its core job is to predict the most likely next token given everything before it, then repeat until the answer is finished.
That sounds too simple to produce a coherent essay. But predicting text well forces a model to pick up grammar, facts, and common reasoning patterns from its training data. It has no database of answers to look up, only a compressed statistical memory of how language tends to flow.
A model also works within a context window, the amount of text it can consider at once. Anything outside that window, such as an earlier conversation, is invisible to it unless the software feeds it back in. That is why a chatbot can seem to forget what you said ten pages ago.
Transformers and Attention
Most modern language models use the transformer design, introduced in the 2017 paper “Attention Is All You Need” by researchers at Google. Its attention mechanism lets the model weigh which earlier words matter most for the word it is about to produce. In “The trophy would not fit in the suitcase because it was too big,” attention helps the model connect “it” to the trophy.
Fine-Tuning and Human Feedback
A model trained only to predict text can ramble or produce harmful content. So developers add a second stage where people write ideal answers and rank model outputs, and the model is tuned to prefer the higher-ranked ones. OpenAI described this method, called reinforcement learning from human feedback, in its 2022 InstructGPT paper.
The result follows instructions and holds a conversation instead of just continuing your sentence.
Everyday AI Already in Your Routine
You do not need to open a chatbot to meet artificial intelligence. You probably used it before lunch.
Face unlock on a phone compares a mathematical map of your face to a stored one. Google Maps and Apple Maps predict traffic from historical patterns plus live data from phones on the road. Netflix and Spotify rank titles and songs by what similar listeners enjoyed.
Banks score card transactions with fraud models in milliseconds, which is why a purchase in another state can trigger a text asking if it was you. In healthcare, the FDA keeps a public list of AI-enabled medical devices it has authorized, many of them tools that help radiologists read scans.
A Quick Test for the Kind of AI Behind a Tool
Most explainers stop at “AI learns from data.” A more useful habit is asking what the system is actually doing, because that tells you how much to trust it.
If it sorts or scores something, like a spam filter or a credit risk score, it is usually narrow and easy to measure, so its error rate can be tracked. If it predicts a number or event, like a delivery time or a demand forecast, it improves with fresh data and drifts when conditions change.
If it generates new content, like a chatbot or an image tool, it produces plausible output that nobody has verified, so a person should check anything that matters. And if a tool gives the same answer every time for the same input and can state its rule, it is probably plain rule-based software, whatever the marketing says.
Where Artificial Intelligence Gets Things Wrong
Because AI runs on patterns, its failures come from patterns too.
Language models can hallucinate, meaning they produce fluent but false statements, including invented citations. In the 2023 federal case Mata v. Avianca, a New York court sanctioned two lawyers who filed a brief containing fake case citations generated by ChatGPT.
Bias comes from data. Reuters reported in 2018 that Amazon scrapped an experimental recruiting tool after it learned to downgrade résumés containing the word “women’s,” because it had been trained on a decade of mostly male applicants.
Brittleness shows up when real inputs differ from the training data. A driving model trained mostly on daytime footage may struggle at night, and a fraud model built before a new scam appears will miss it.
Underneath all of it, the system tracks likelihood, not truth. The NIST AI Risk Management Framework, released in January 2023, treats testing, monitoring, and human oversight as ongoing work, not a one-time check.
Does AI Actually Understand Anything?
Researchers disagree. Chatbots show real skill on many reasoning tasks, yet they also fail at simple things in ways a person would not. Whether that counts as understanding is still debated among cognitive scientists and AI researchers, and a confident answer in either direction goes past the evidence.
For practical purposes, treat AI as a fast, tireless pattern engine that is often right and sometimes confidently wrong. Use it for drafts, summaries, sorting, and first passes, and keep a knowledgeable person in charge of anything involving health, money, or legal decisions.
Once you know how artificial intelligence works under the hood, it gets easier to tell which jobs to hand it and which ones still need you.